Exploring the TypeScript Compiler Part 6: What Go Unlocks
This is Part 6, the final part of an expanded and revised version of the tskaigi 2026 Day 2 talk, “A History of TypeScript Compiler Design Through Constraints and Historical Context”. It includes explanations and short stories that were cut from the talk because of time.
- Part 0: Overview
- Part 1: Why Go?
- Part 2: Inside the TypeScript Compiler
- Part 3: Why TypeScript?
- Part 4: Roslyn and the Red-Green Tree
- Part 5: JavaScript Madness🫠
- Part 6: What Go Unlocks
On March 11, Microsoft announced that it was porting the TypeScript compiler to Go. The reported numbers were close to a tenfold speed increase, even for large repositories such as VS Code and Playwright.
It is easy to say that it became faster because it was written in Go. This part looks more closely at what changed and how those changes improved speed.
In the interview below, Anders Hejlsberg says native code brings a 3.5-fold gain and parallel work brings another 3.5-fold gain, for roughly a tenfold gain overall.
Here, “native code” includes both compiling to machine code and improving memory layout with Go structs.
Machine Code
The earlier TypeScript compiler was a JavaScript program run by Node.js. Before it could start its main work, it went through these steps:1
- Start Node.js.
- Load
tsc, written in JavaScript, and have V8 turn it into bytecode. - Run the bytecode and compile parts of it with a JIT compiler when needed.
Go code is compiled to machine code ahead of time. At runtime, it does not have to load JavaScript, turn it into bytecode, or wait for JIT optimization.
Value Types
Go's struct is a value type. When one struct is stored directly in a field of another, its contents can be placed inside the outer struct's memory area.
Here is the definition of an AST node in typescript-go:
type Node struct {
 Kind   Kind // int16
 Flags  NodeFlags // uint32
 Loc    core.TextRange // Another struct
 id     atomic.Uint64 // Another struct
 Parent *Node // Reference to the parent node
 data   nodeData // interface
}
This gives us the following picture of how the data is placed in memory:
Primitive values such as int16 and uint32 are placed next to each other. The same applies to the embedded structs TextRange and atomic.Uint64. Parent stores a pointer rather than the whole parent node because the nodes refer to each other in a cycle.
In JavaScript, the layout is different:
// Shortened example
interface Node extends ReadonlyTextRange {
  kind: SyntaxKind; // Numeric enum
  flags: NodeFlags; // Numeric enum
  pos: number; // Go version: Loc.Pos()
  end: number; // Go version: Loc.End()
  id?: NodeId; // number
  parent: Node; // Reference to the parent node
}
Its layout in memory looks like this:
In JavaScript, primitive values can be stored next to each other. But when one object contains another object, it holds a reference to that object rather than the object's data itself.
This matters when the program reads the data. If values are close together, one memory fetch can bring nearby values into the cache. If objects are spread across the heap, the program has to follow references to reach them.
Controlling Data Layout
Go gives us detailed control over data layout that is difficult to achieve with ordinary JavaScript objects. One example is the use of an Arena in a broad sense.
The team found that 30–40% of the nodes in a compilation were Identifiers. If every node is allocated as a separate object on the heap, the garbage collector has too many individual allocations to manage, which hurts performance.
To address this, the compiler uses a slice called Arena to store nodes of the same type together. This greatly reduces the number of small, separate allocations. The structure itself is very simple:
type Arena[T any] struct {
 data []T
}
Instead of allocating each node separately, the compiler stores nodes in an Arena that has space for many values of the same type. The Arena grows as elements are added. When its current space is full, it allocates new space for later nodes.
Suppose there are one million Identifier nodes. Allocating them one by one on the heap would require one million separate allocations. If each allocated area holds 256 nodes,2 a rough estimate is one million divided by 256, or about 4,000 allocations.
The current implementation also uses Arenas for several node types other than Identifiers.3
Shared-Memory Multithreading
Parallel processing accounts for the other 3.5× speedup. The JavaScript version runs on a single thread and does not process this work in parallel, which became a bottleneck. In 2026, JavaScript can use the Worker Threads API and SharedArrayBuffer for shared-memory parallelism. But SharedArrayBuffer has many restrictions, making it very difficult to represent a large graph full of references.
Go provides built-in support for this kind of parallel processing. The following diagram shows an example of how type checking can run in parallel.
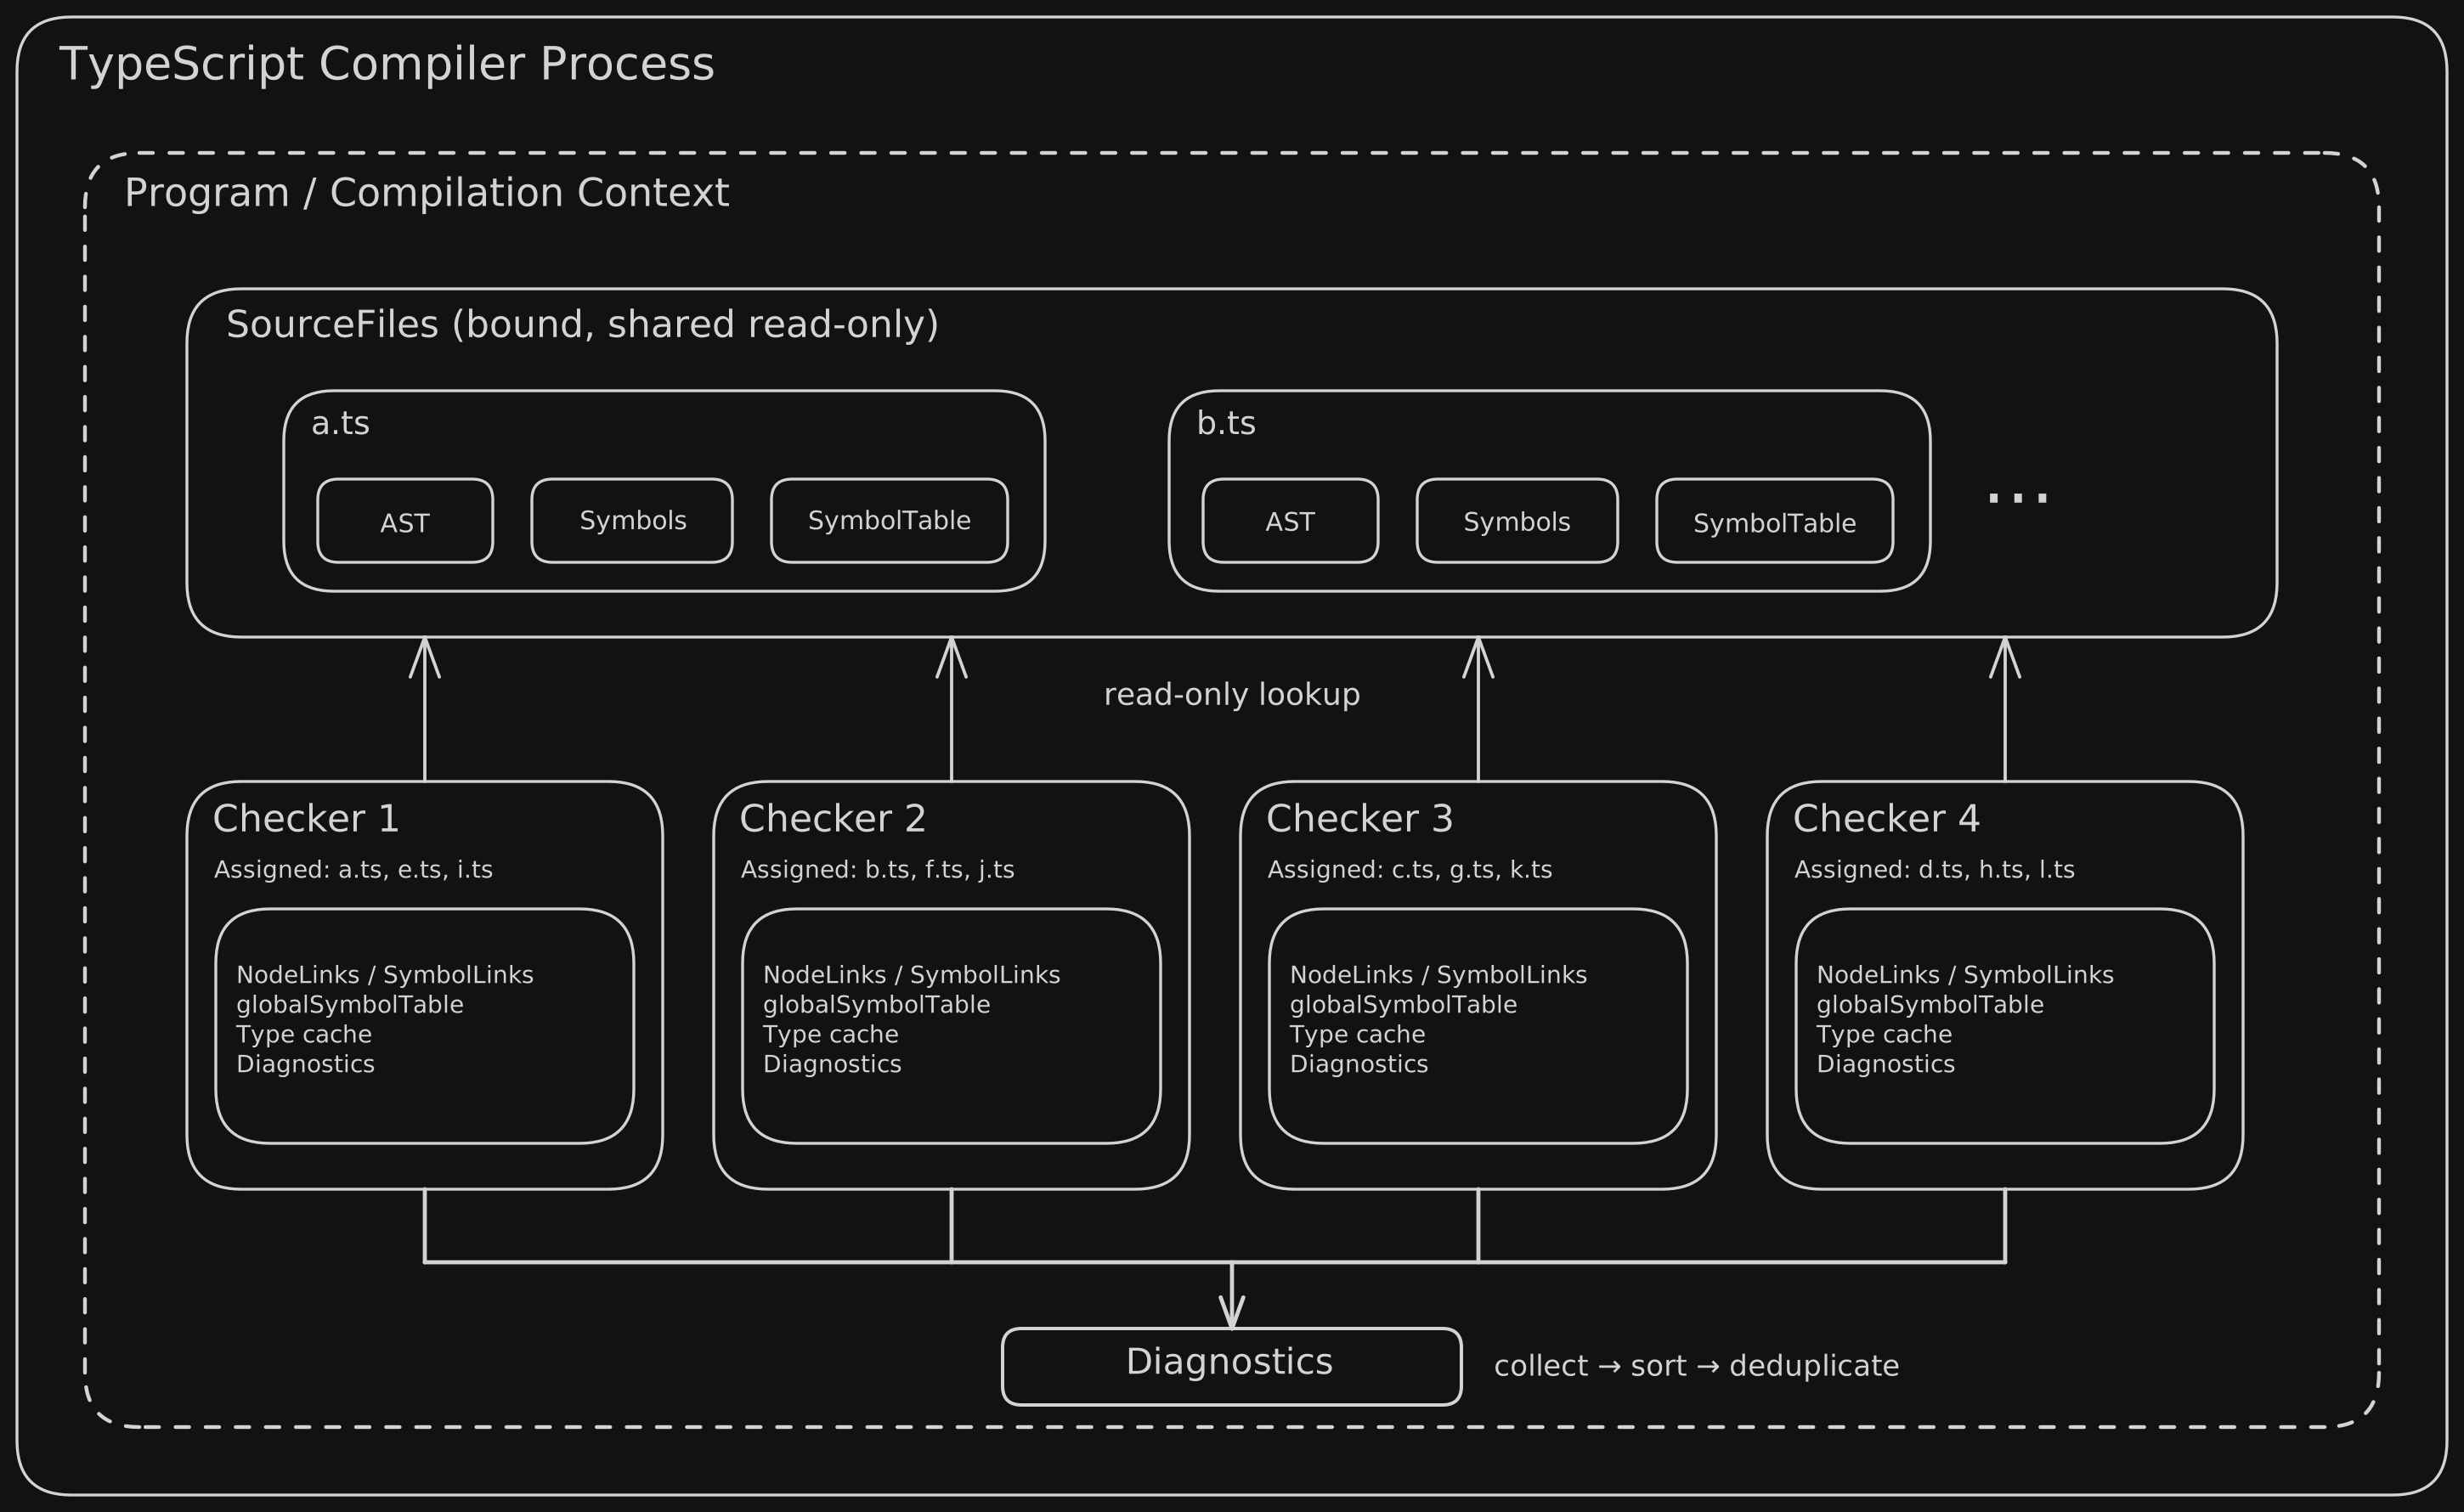
By default, there are four Checkers, and each is assigned its own files. As explained in Part 2, a Checker walks the bound AST and Symbols to resolve types. I have often pointed out that the TypeScript AST is not immutable. During type checking, however, the bound syntax and declaration information is not changed, so multiple Checkers can read it at the same time.
Another important point is that the Checkers share bound Symbols, but they do not share the Symbols, Types, or caches that each Checker creates while calculating types. They accept some duplicate work so that each Checker can focus on its assigned files. The team judged that the benefit of running in parallel without synchronizing shared caches was greater than the cost of resolving some types more than once.
This design has a tradeoff: it can use a lot of memory. The blog post below explains that libraries such as zod and drizzle make extensive use of TypeScript's type system. Resolving their types creates many values, so each Checker can consume a large amount of memory.
https://zackoverflow.dev/writing/why-does-tsgo-use-so-much-memory
Summary
Across Parts 1–6, we have looked at how the TypeScript compiler works, its history, comparisons with other compilers, the limits of JavaScript, and the improvements made possible by Go. With all of that in mind, I think the reasons for porting it to Go can be summarized as follows:
- Because of the circumstances at the time, TypeScript began as an extension of existing JavaScript.
- The compiler was written in JavaScript and designed from the start to work well with editors and IDEs. This led to an unusual design shaped by JavaScript's limits.
- A complex type system was built on top of that design, and performance limits became clear in large projects.
- A port was chosen over a rewrite to preserve the compiler's complex behavior.
- Go has garbage collection, which makes it easier to keep the existing reference structures. Its coding style also suited the port.
- By keeping the existing structure while adding native execution, better memory layout, and parallel processing, the port can reduce the impact of JavaScript's limits.
Footnotes
-
For an overview, I recommend An Introduction to Speculative Optimization in V8 by Benedikt Meurer. ↩
-
The implementation sets a maximum of 256, but I do not know why that value was chosen. https://github.com/microsoft/TypeScript/blob/673a5f17d713bdc8c7185f18a9c11e3c4ac5d781/tsc/internal/core/arena.go#L61-L66 ↩
-
https://github.com/microsoft/TypeScript/blob/673a5f17d713bdc8c7185f18a9c11e3c4ac5d781/tsc/internal/ast/ast_generated.go#L20-L73 ↩